Your phone, your AI.
tensai runs open models directly on your Android phone. Chat, reasoning and an agent that can act, with nothing leaving the device unless you ask for it.
Pre-1.0, expect changes
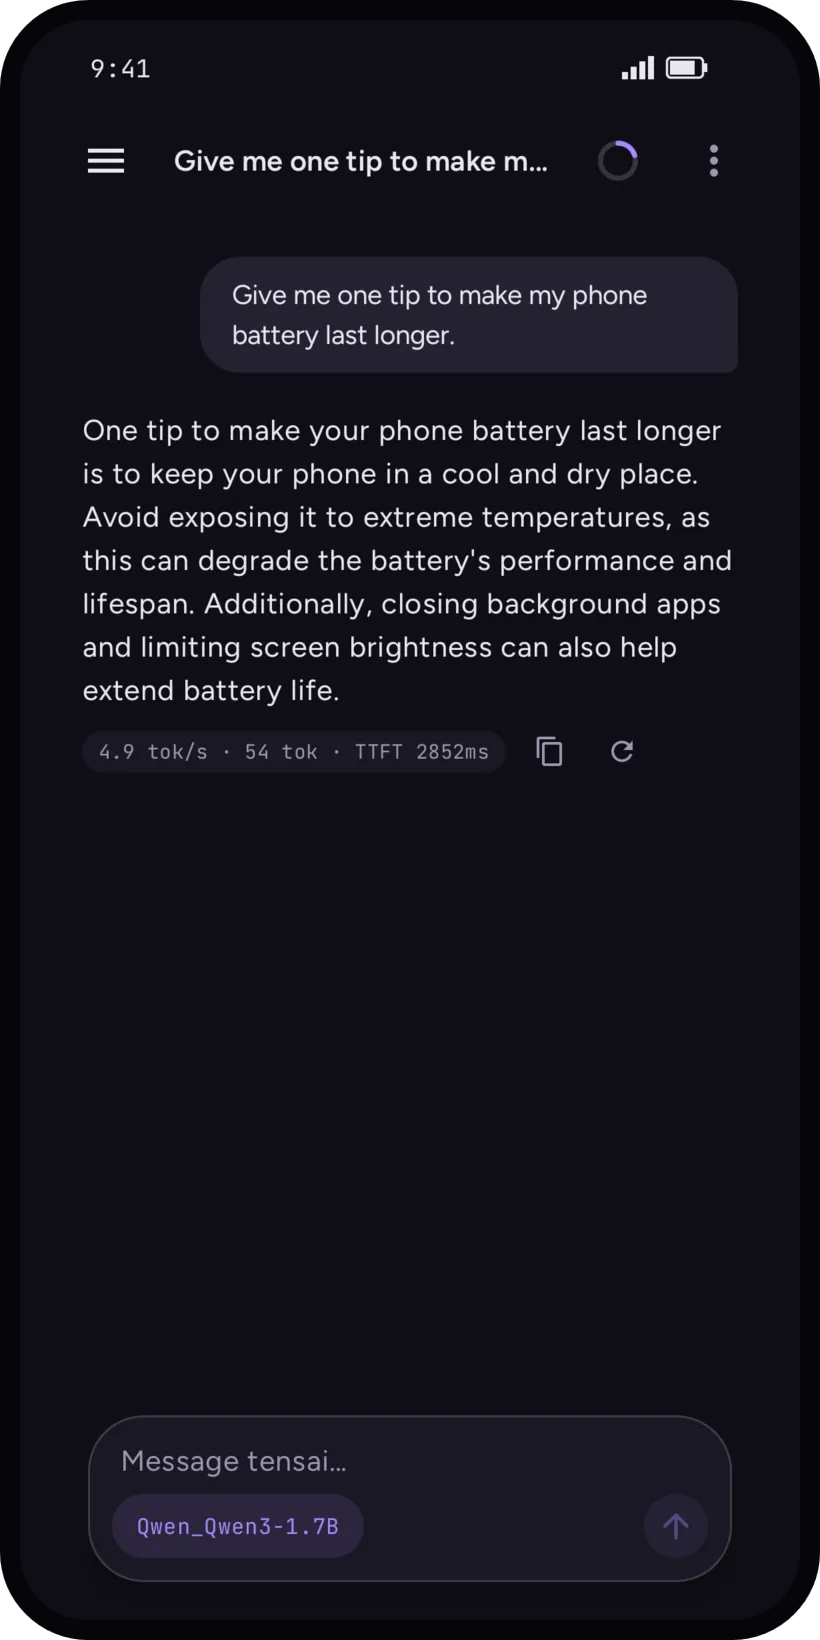
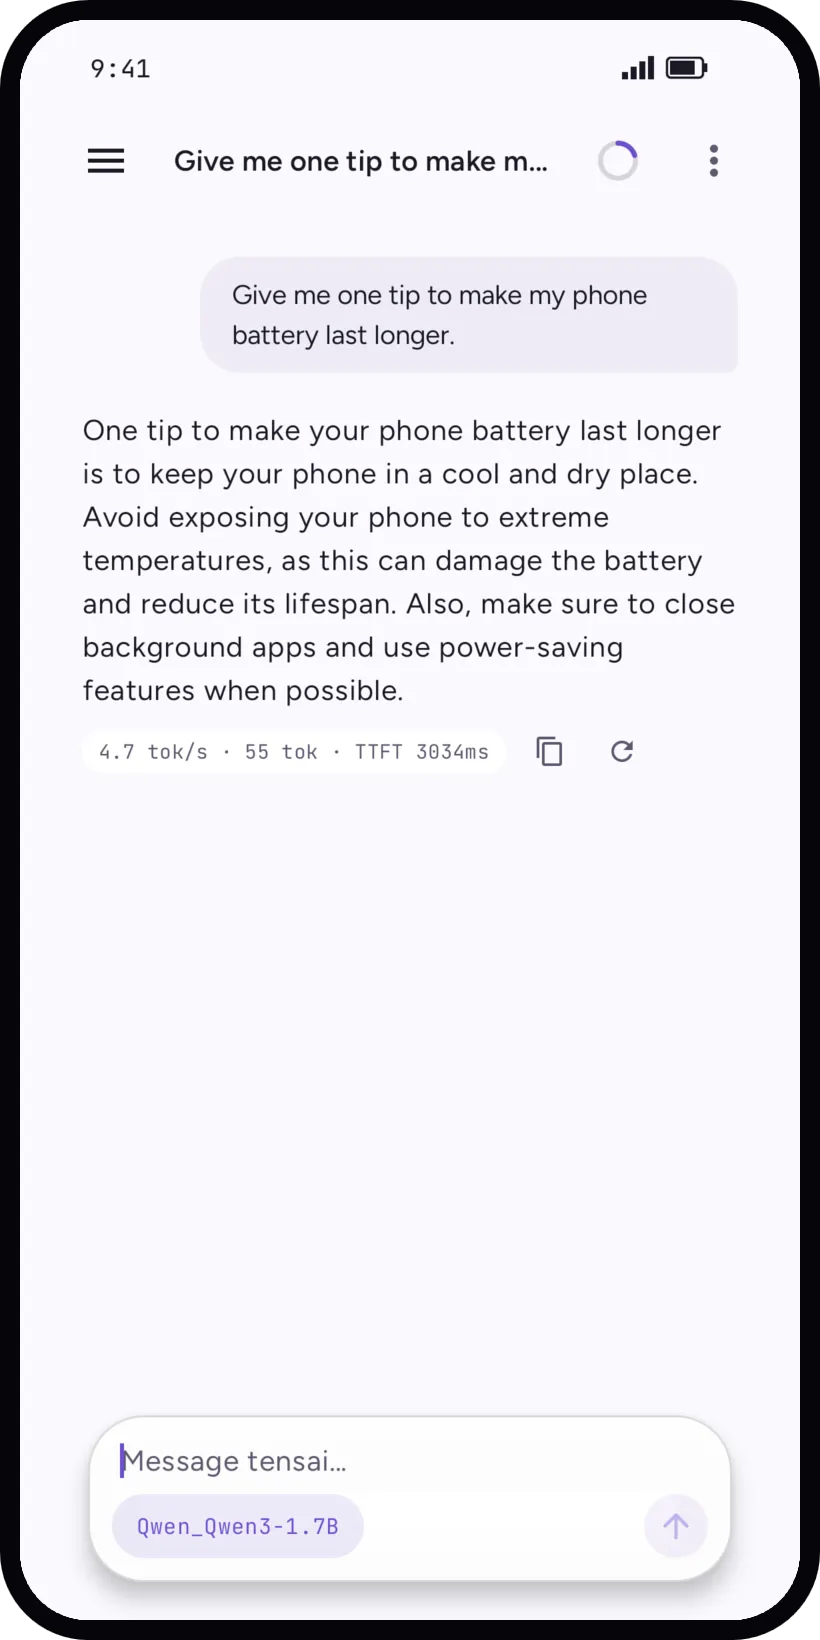
On the device
Models run on your phone's CPU or GPU through llama.cpp. Once a model is downloaded, tensai works offline.
Any open model
Import a GGUF file or pick one from Hugging Face. A fit check rates it against your phone's memory.
- Runs well
- Tight fit
- Won't fit
An agent, with guardrails
Tools for dates, maths, memory, timers, calendar and messages. Anything that sends or deletes asks you first. Internet tools stay off until you enable them.
What it looks like
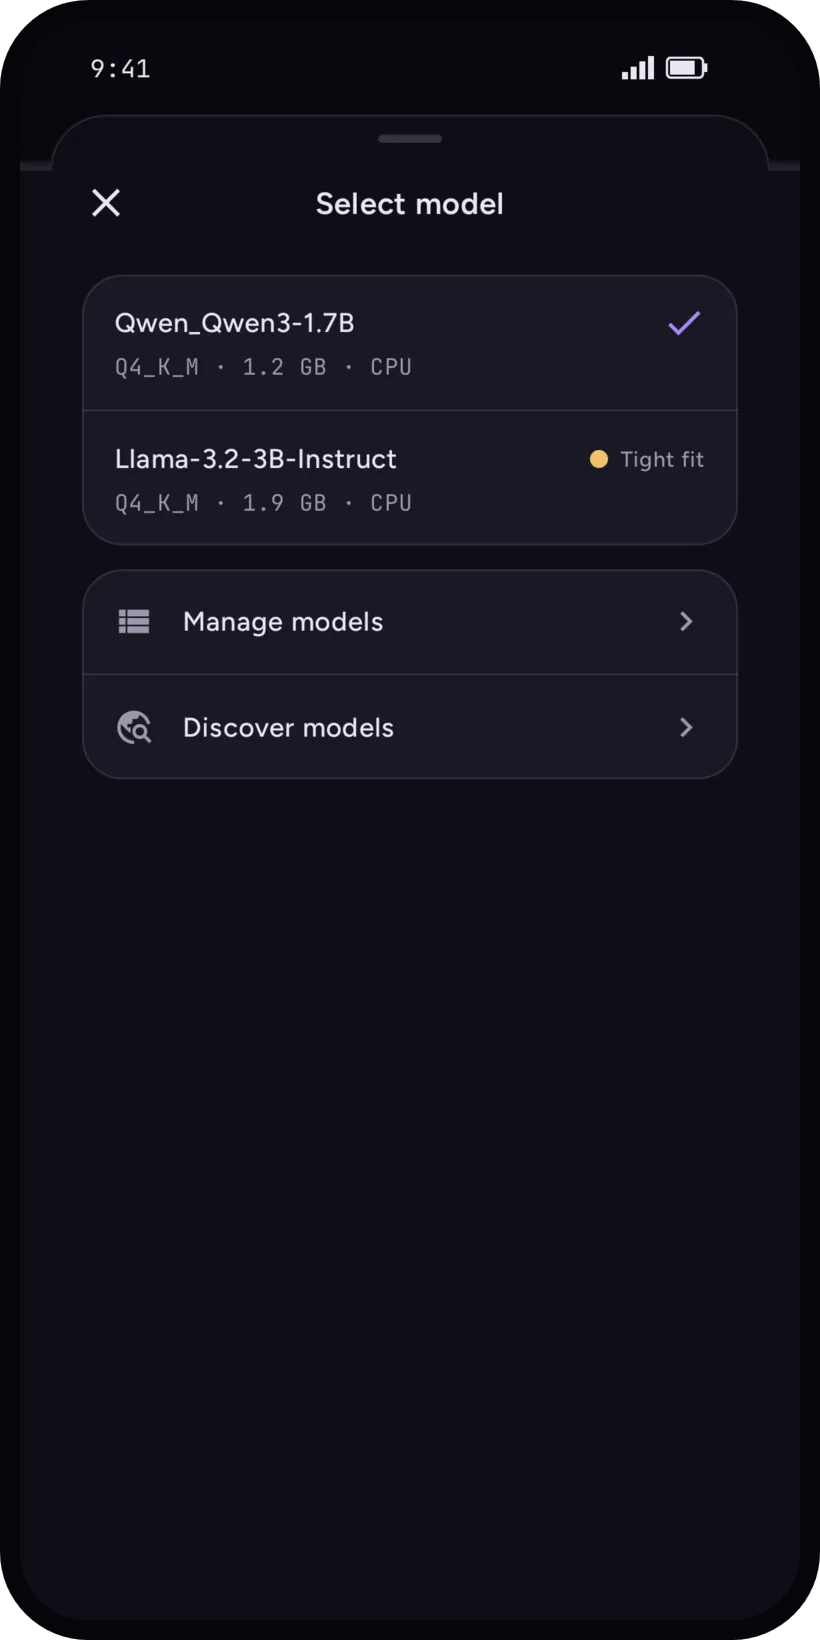
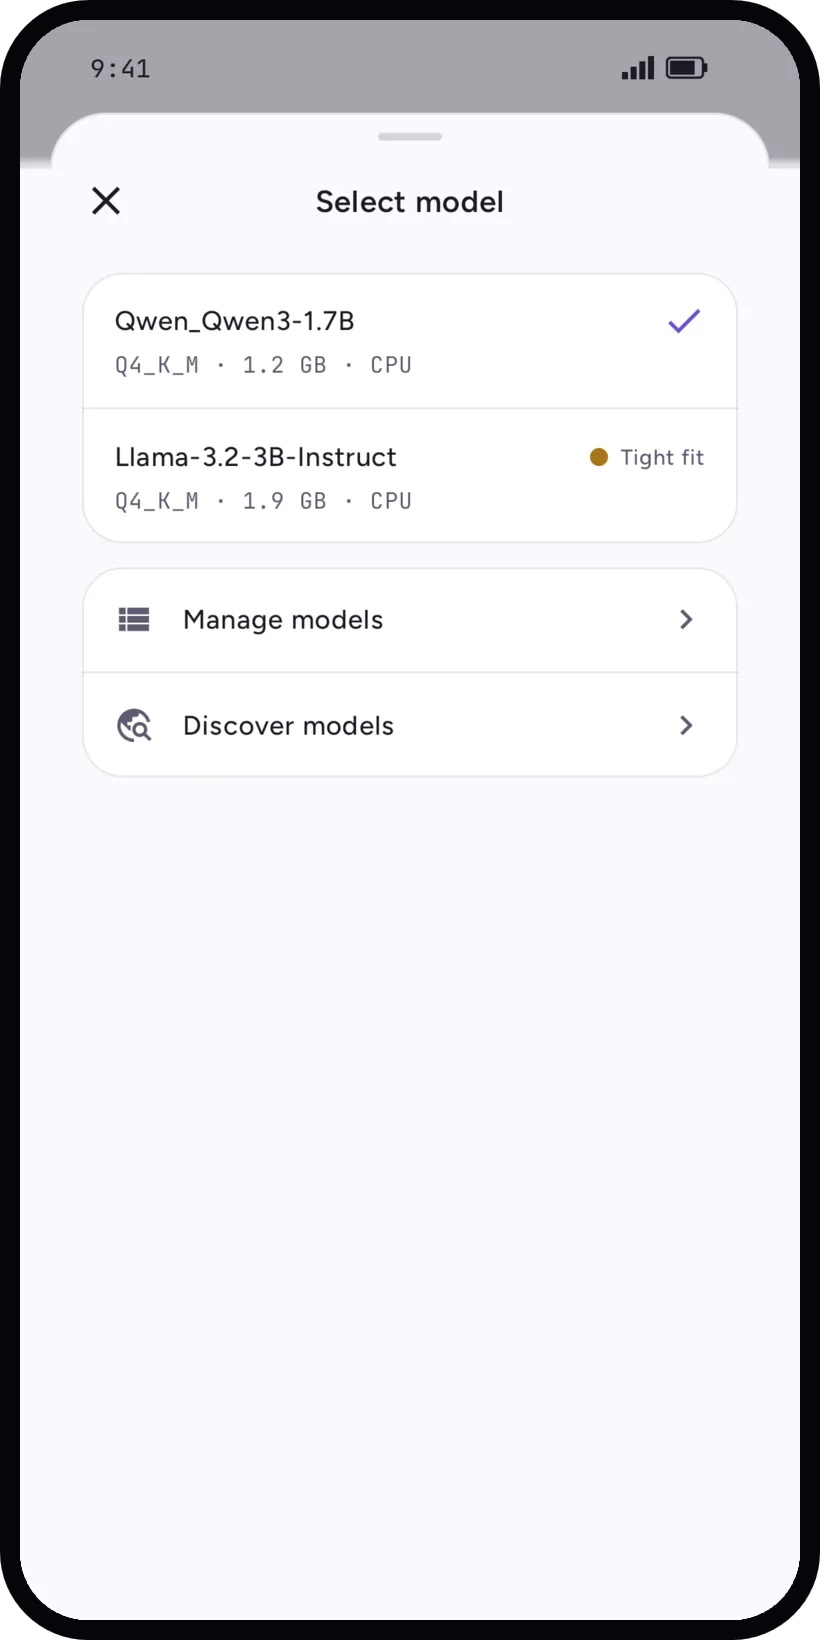
Pick a model. The fit check shows what your phone can run. 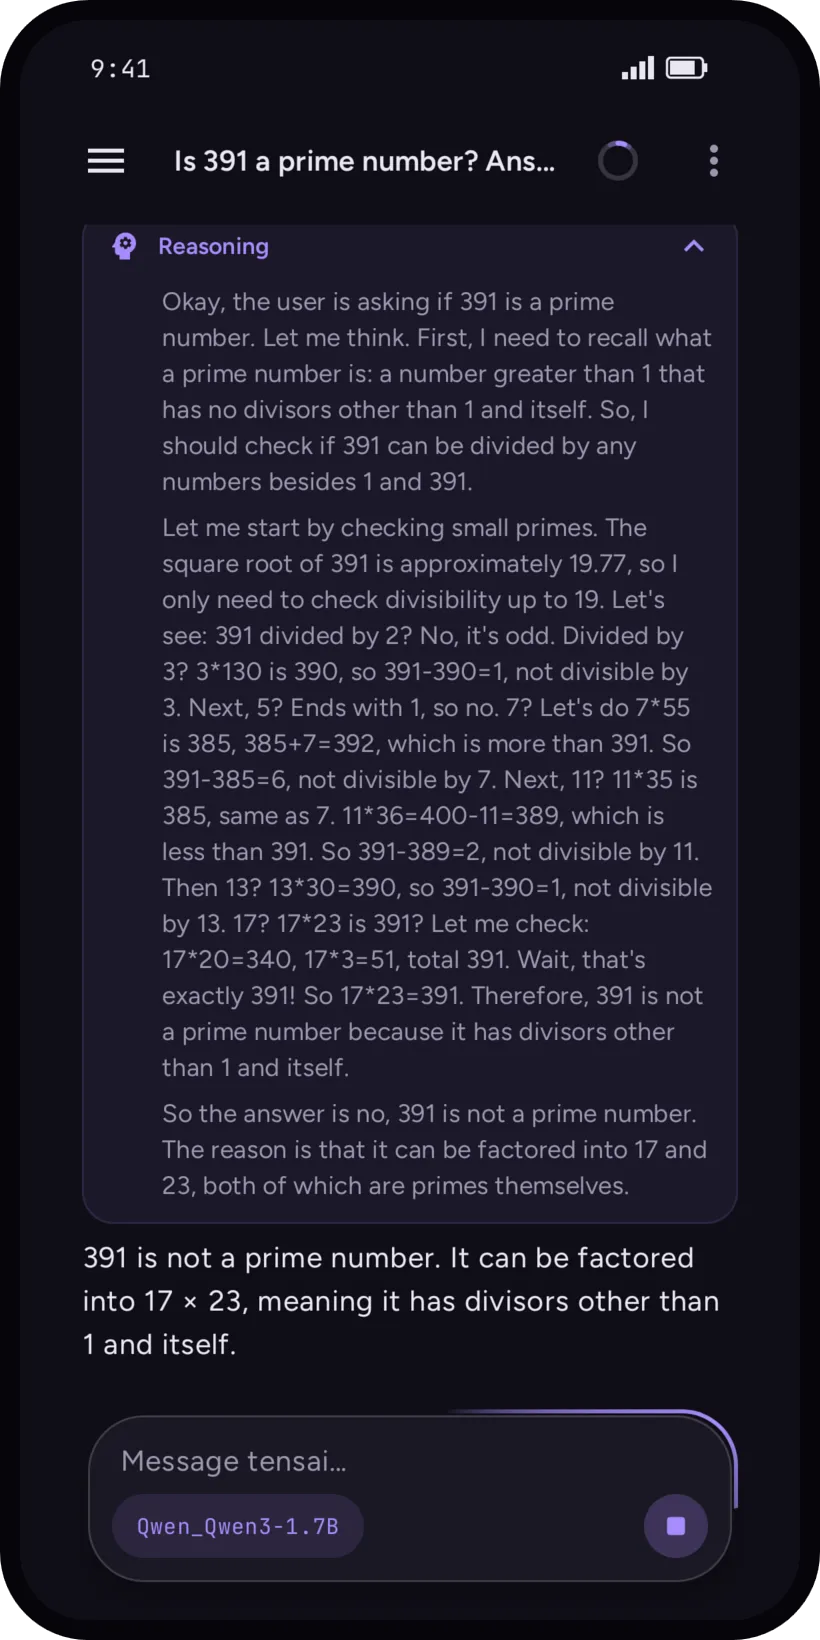
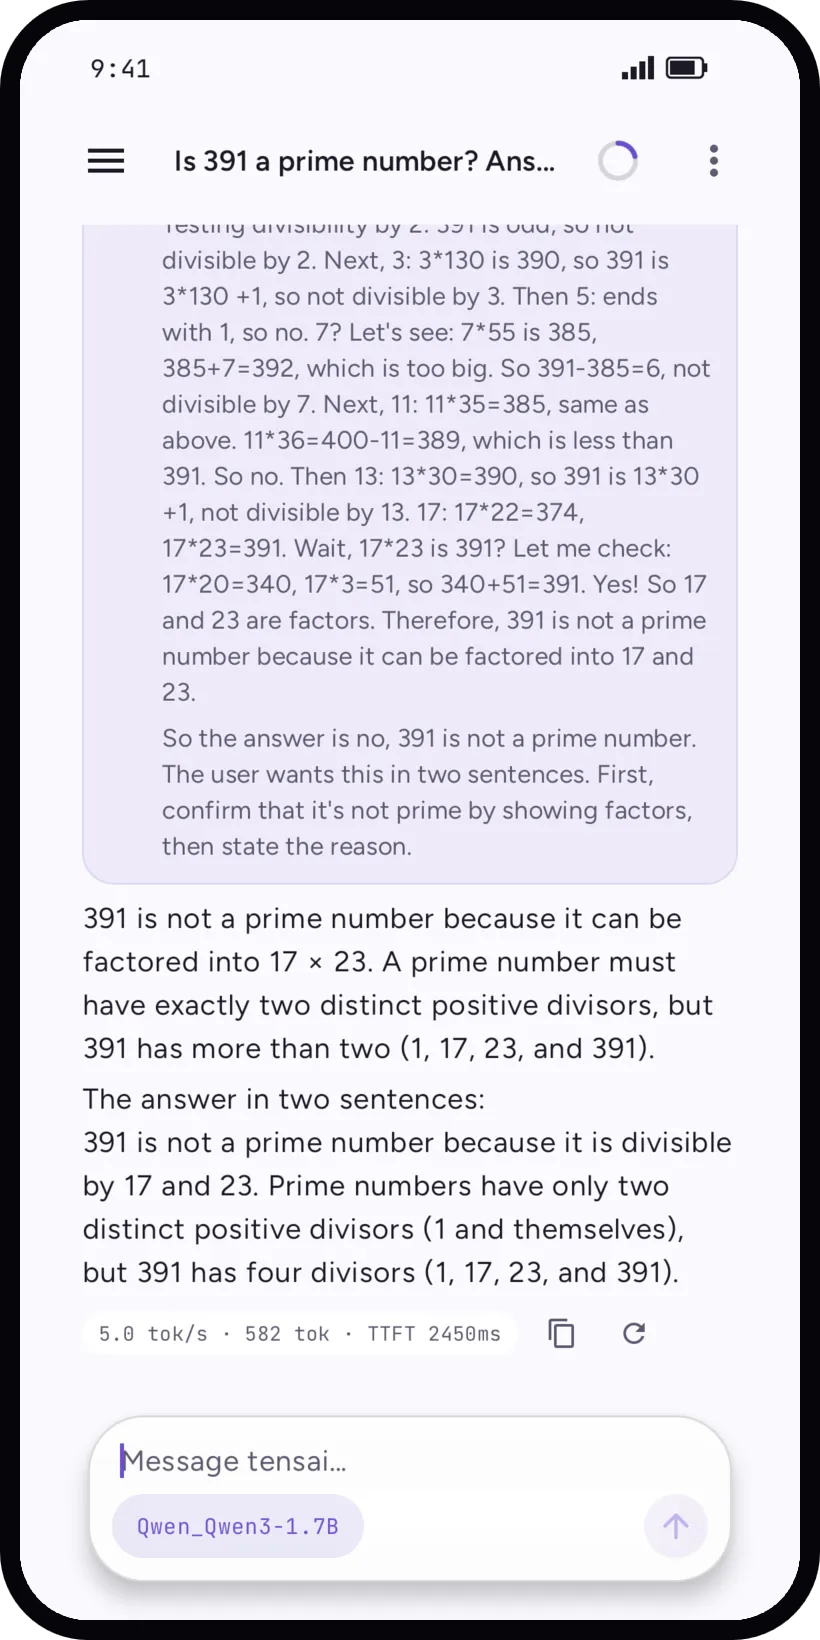
Read the model's reasoning, or fold it away. 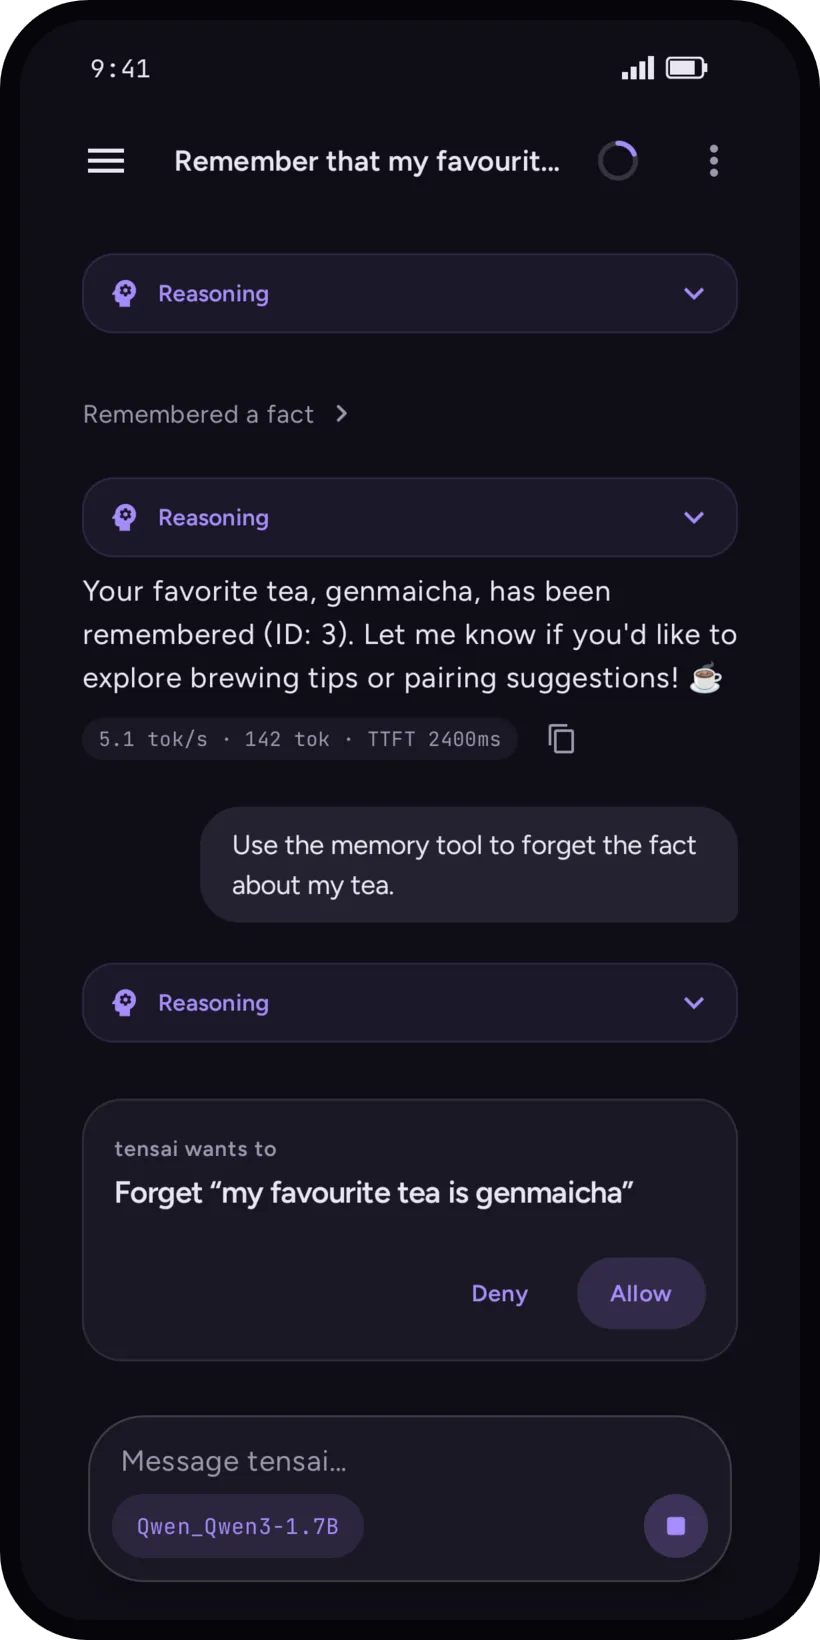
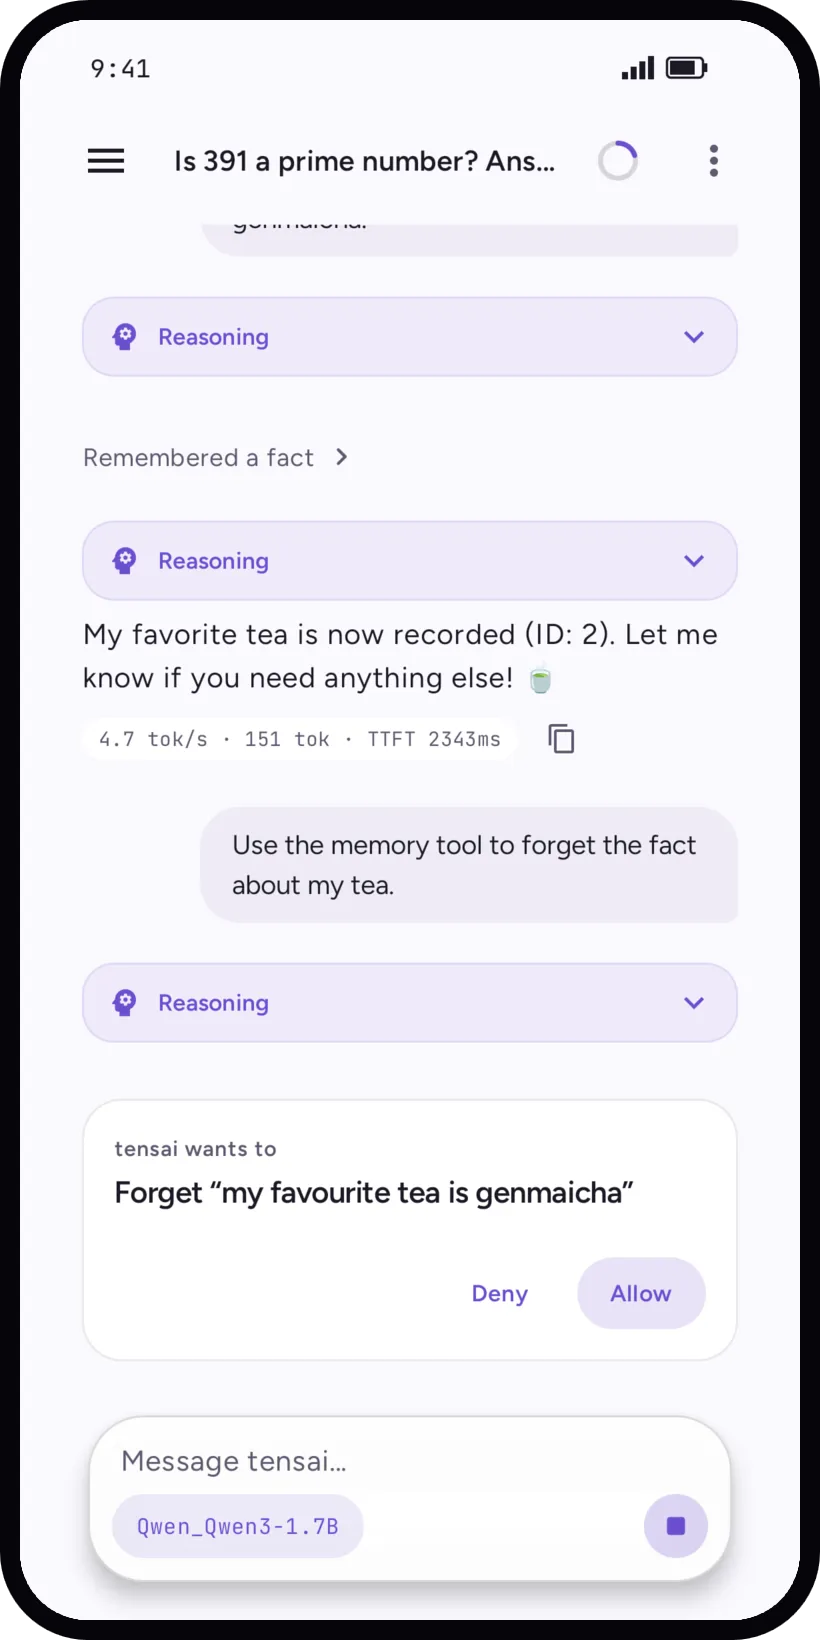
Anything that deletes or sends waits for your answer. 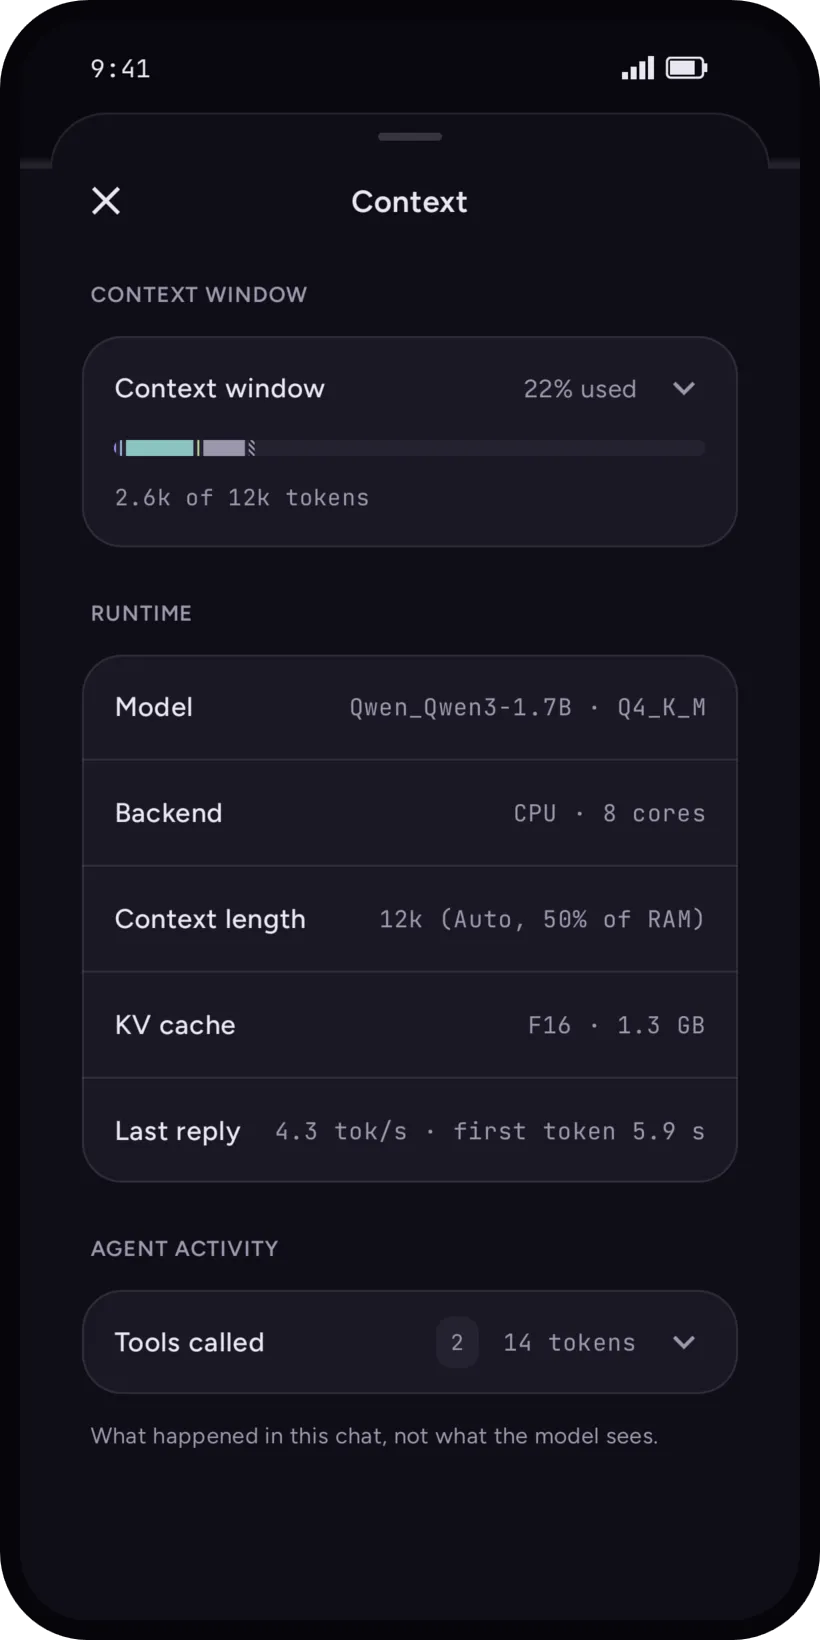
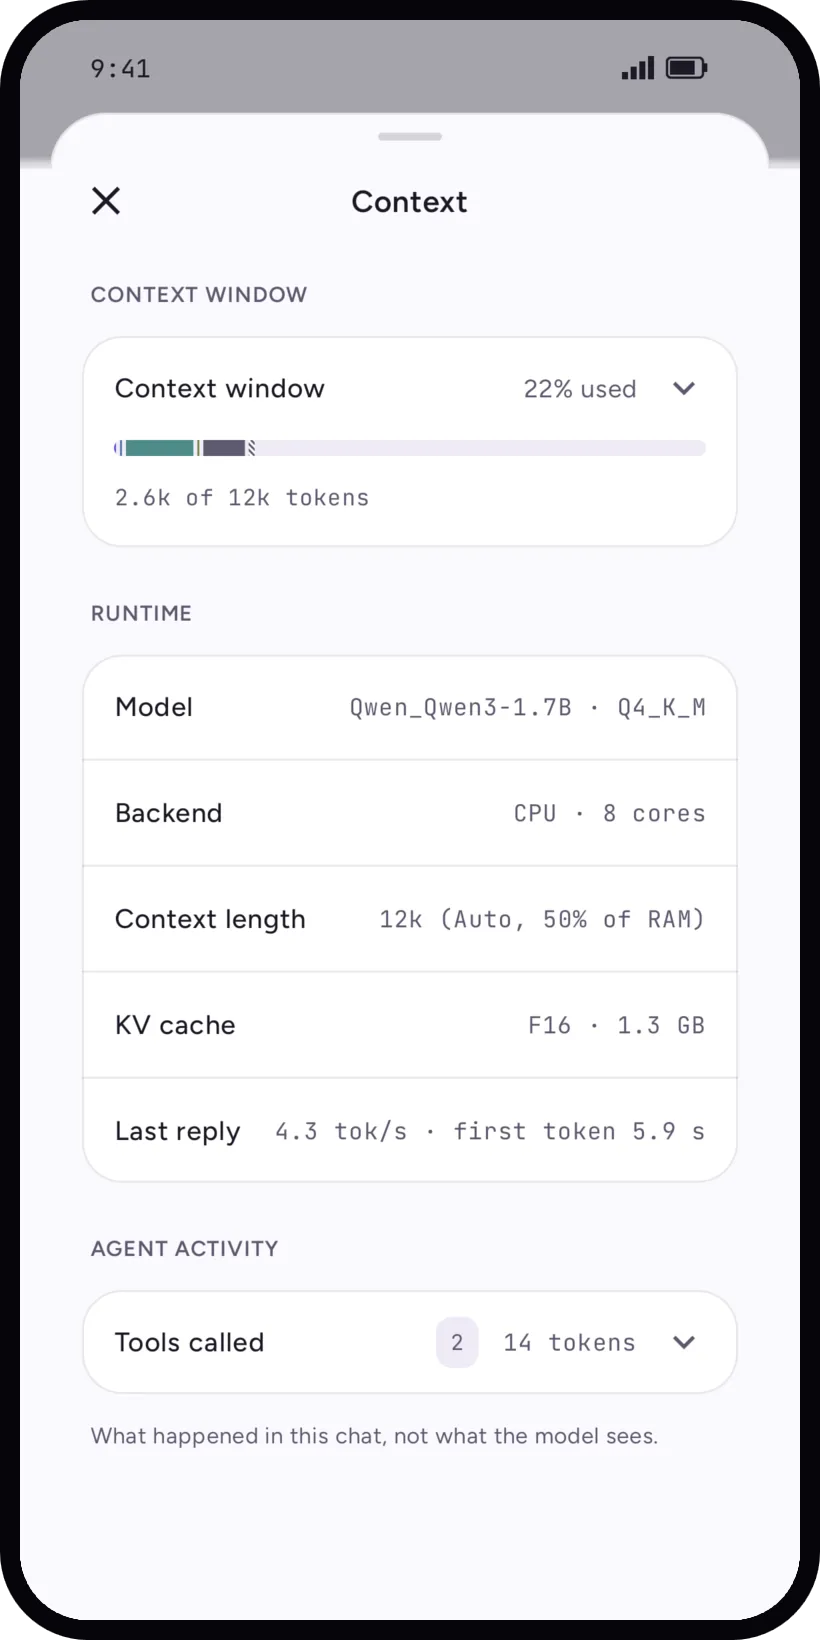
See what fills the context, agent activity included.
Measured
Your phone will differ. Big models are slow on phones; tensai tells you before you download.
Dimensity 900 · Qwen3 1.7B Q4_K_M · CPU
| first message once ready | ~1 s |
|---|---|
| reply speed | ~5.5 tok/s |
| model load | ~7 s |
The tool list is prepared in the background after loading, about a minute on this phone.
Coming next
- MCP and skills
- 1.0: stable release
- API server on your network
Apache 2.0. The app and the engine, llama.kt, are on GitHub.